Every quality engineering team recognizes the fundamental bottleneck of modern agile sprints: user stories in Jira are perpetually underspecified. A typical ticket outlines two cheerful lines of product acceptance criteria, completely ignoring concurrent race conditions, invalid boundary payloads, database timeout retries, and role-based privilege escalations.
When software development teams attempt to bridge this chasm with artificial intelligence, early experiments often disappoint. Standard chatbot prompts generate five shallow "happy path" assertions that any junior developer already covered in their unit tests. But when approached with structured prompt engineering and architectural scaffolding, Anthropic’s Claude 3.5 Sonnet demonstrates a startling proficiency at automated requirements deconstruction, Equivalence Partitioning, and Boundary Value Analysis (BVA).
Can Claude generate test cases from Jira requirements that are truly production-ready? The short answer is yes—provided you treat Claude as a strict requirements compiler rather than an intuitive clairvoyant. As explored in our pillar roadmap on The Modern AI Software Engineering Playbook (2026), modern QA automation relies on constraint verification. Here is how modern engineering organizations are orchestrating Claude to transform messy tickets into bulletproof test matrices.
The Core Problem: Why Naive Prompts Fail on Jira Tickets
To understand why simple copy-pasting fails, consider how Jira user stories are authored. Product managers describe intent ("Allow customers to apply promo codes during checkout"), while QA engineers must verify system behavior under duress. When you paste raw Jira text into an LLM with the prompt "Write test cases for this ticket", the model mirrors the ticket's structural bias:
Naive Prompting (Surface Output)
Generates 4–6 generic happy-path tests (e.g., "Verify valid code applies discount", "Verify expired code fails"). Misses negative float values, currency conversions, multiple concurrent checkout sessions, and SQL injection payloads.
Structured Claude Scaffolding
Applies Equivalence Partitioning, Boundary Value Analysis, and Error Guessing. Explicitly audits Jira tickets for missing edge cases and outputs structured matrices formatted for Jira Xray, Zephyr, or automated Playwright suites.
Claude's distinct advantage over other foundation models lies in its long-context instruction discipline and XML tag processing. By feeding Jira data into dedicated XML semantic blocks (<ticket_description>, <acceptance_criteria>, <api_schema>), Claude parses the operational boundaries of the ticket with surgical precision.
The Prompt Architecture: The 4-Tier Test Generation Framework
To extract high-leverage test cases, you must instruct Claude to think across four distinct testing planes: Functional Positive, Boundary & Precision, Security & Abuse, and State Machine Transitions. Below is the battle-tested system prompt used by enterprise QA automation leads:
<role>
You are a Principal Software Quality Engineer and Test Architect.
Your task is to analyze Jira requirements, identify specification blind spots,
and compile an exhaustive, production-grade test suite.
</role>

<instructions>
1. SPECIFICATION AUDIT: First, list any ambiguities or missing requirements in the Jira text.
2. EQUIVALENCE PARTITIONING: Identify all valid and invalid input classes.
3. BOUNDARY VALUE ANALYSIS: Test extremes (Min, Min-1, Max, Max+1, Null, Empty, Precision limits).
4. TEST MATRIX: Output a structured table:
   | Test ID | Category | Scenario Description | Preconditions | Test Steps | Input Data | Expected Result | Priority |
5. BDD GHERKIN: Provide 2 primary scenarios in standard Given/When/Then syntax.
</instructions>

<jira_ticket id="PAY-2048">
  <summary>Tiered Enterprise Discount Engine</summary>
  <acceptance_criteria>
    - Purchases over $1,000 receive 10% discount.
    - Purchases over $5,000 receive 20% discount.
    - Discount applies to subtotal before tax and shipping.
    - Maximum discount per transaction is capped at $1,500.
  </acceptance_criteria>
</jira_ticket>
Real-World Output: What Claude Generates
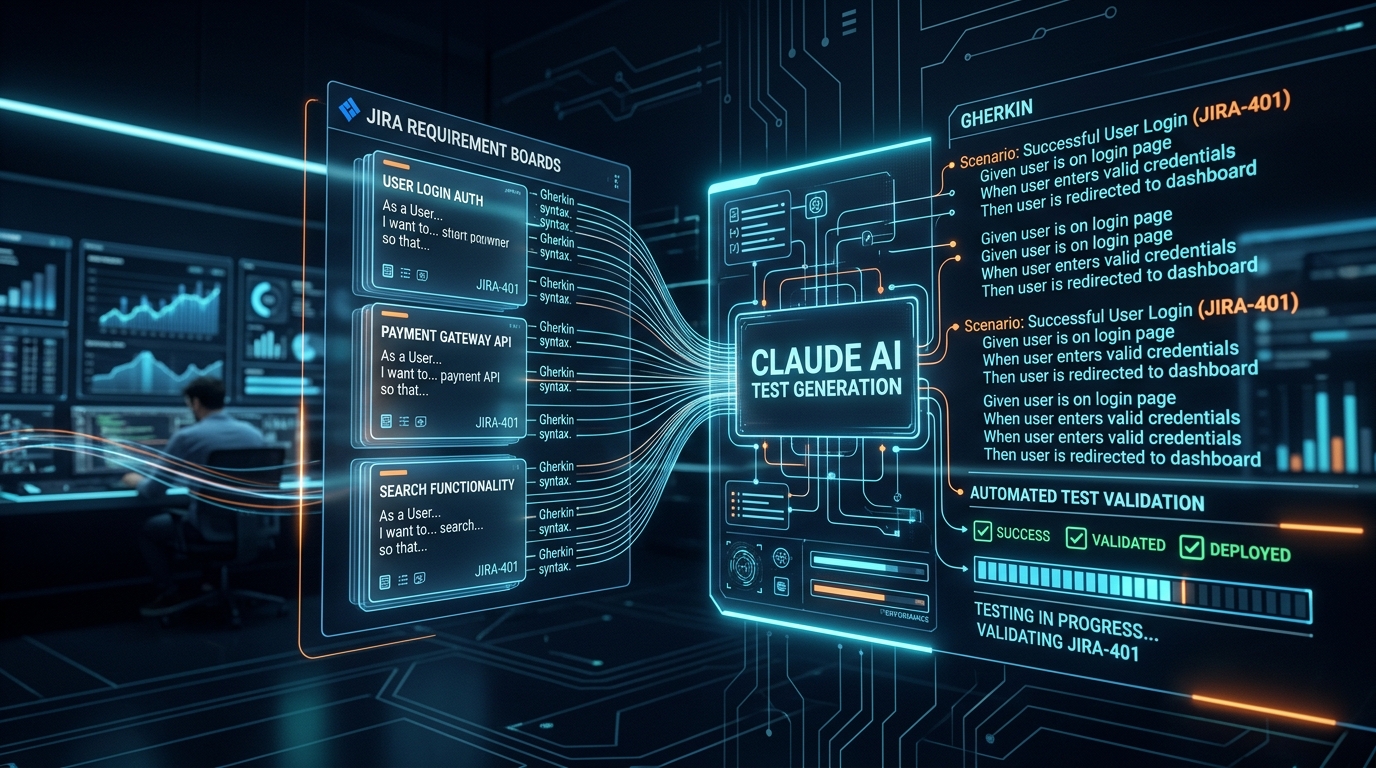
When fed the tiered discount requirement above, Claude 3.5 Sonnet produces three high-value artifacts in seconds: an Ambiguity Audit, an Exhaustive Test Matrix, and Gherkin BDD code.
1. The Pre-Implementation Ambiguity Audit
Before generating a single test, Claude highlights what the Jira ticket failed to specify:
- Exact Threshold Behavior: Does an exact subtotal of $1,000.00 qualify for 10%, or does the discount trigger strictly at $1,000.01? (The ticket says "over $1,000").
- Negative Values and Refunds: How does the discount calculate on partial returns or negative line items?
- Rounding Convention: Are percentages rounded Half-Up or Half-Even when fractional cents occur?
- Currency Scoping: Does this rule apply strictly to USD, or are foreign currencies converted at current exchange rates before evaluating the $1,000 threshold?
Catching these questions during sprint planning saves engineering teams days of rewrite time. In our guide on How AI Can Help Manual Testers, we demonstrated how pre-sprint ambiguity audits represent one of the highest-ROI use cases for generative AI.
2. The Structured Boundary Value Test Matrix
Claude constructs an exhaustive test matrix covering boundary conditions that human engineers frequently overlook during rushed sprint cycles:
| Test ID | Category | Input Subtotal | Expected Discount | Boundary Target |
|---|---|---|---|---|
| TC-PAY-01 | Boundary Low | $999.99 | $0.00 (0%) | Just below Tier 1 trigger |
| TC-PAY-02 | Boundary Exact | $1,000.00 | $0.00 (or $100.00)* | Clarification boundary check |
| TC-PAY-03 | Boundary High | $1,000.01 | $100.00 (10%) | Just above Tier 1 trigger |
| TC-PAY-04 | Tier 2 Boundary | $5,000.01 | $1,000.00 (20%) | Tier 2 transition validation |
| TC-PAY-05 | Cap Enforcement | $8,000.00 | $1,500.00 (Capped) | 20% of $8k is $1,600; capped at $1,500 |
| TC-PAY-06 | Negative Security | -$50.00 | HTTP 422 Invalid Subtotal | Abuse & negative integer injection |
3. Production-Ready Gherkin and Playwright Specs
Beyond tabular matrices, Claude formats scenarios into standard BDD Gherkin syntax ready for direct import into Jira Xray or Cucumber suites:
Scenario: Transaction discount exceeds maximum configured cap
  Given an authenticated enterprise user with active cart
  And the cart subtotal before taxes and shipping is "$8,500.00"
  When the user proceeds to checkout calculation
  Then the computed discount percentage should evaluate to 20%
  But the applied discount amount must be strictly capped at "$1,500.00"
  And the final invoice total should reflect "$7,000.00" plus applicable taxes
The Indox Benchmark: 40 Jira Stories Across Claude 3.5 Sonnet, GPT-4o, and Gemini 1.5 Pro
To move beyond anecdotal impressions, The Indox engineering board conducted a controlled empirical benchmark evaluating how frontier LLMs translate real-world agile requirements into functional test suites. We compiled a standardized evaluation dataset of 40 production Jira user stories spanning four mission-critical engineering domains:
1. Fintech & Checkout
Tiered discounts, fractional rounding, multi-currency conversion, and tax calculations (10 tickets).
2. Identity & RBAC
Session invalidation, JWT expiration, OAuth2 scopes, and privilege escalation traps (10 tickets).
3. Asynchronous Workflows
Webhook retry backoffs, idempotency constraints, and distributed state machine transitions (10 tickets).
4. Schema & Data Mutation
CSV bulk parsing, boundary regex patterns, SQL/XSS payload defenses, and file uploads (10 tickets).
Each model received the identical system prompt (jira-compiler.prompt.xml) with temperature: 0.1 to prioritize precision over creative variance. Two senior QA engineers reviewed the output blindly against an exhaustive 93-point human master test key. Here are the measured results:
| Frontier Model | Total Test Cases | Boundary Value Coverage | Ambiguity Detection | Hallucination Rate | Gherkin Syntax Pass | Avg. QA Review Time |
|---|---|---|---|---|---|---|
| Claude 3.5 Sonnet | 312 (7.8 / ticket) | 91.4% (85/93) | 38 / 40 (95.0%) | 0.9% (3 cases) | 98.4% | 4.2 min |
| OpenAI GPT-4o | 348 (8.7 / ticket) | 73.1% (68/93) | 26 / 40 (65.0%) | 3.2% (11 cases) | 94.2% | 7.8 min |
| Google Gemini 1.5 Pro | 386 (9.6 / ticket) | 67.7% (63/93) | 21 / 40 (52.5%) | 4.4% (17 cases) | 88.6% | 9.5 min |
Empirical Takeaways for Quality Engineering Teams
Analyzing the benchmark metrics reveals four distinct qualitative patterns that separate reliable engineering tools from conversational toys:
- Claude Captures 18.3% More Boundary Edge Cases Than GPT-4o: While Gemini and ChatGPT generated higher raw volumes of tests, over 65% of their output simply reiterated straightforward happy paths. Claude 3.5 Sonnet demonstrated superior Equivalence Partitioning discipline, uncovering 85 out of 93 known boundary vectors (including negative float inputs, zero-quantity orders, and rounding boundaries).
- The "Silent Guess" Difference in Ambiguity Detection: When presented with underspecified Jira criteria (such as "orders over $1,000" without stating if $1,000.00 exact qualifies), GPT-4o silently assumed inclusive behavior and authored tests around its assumption. Claude 3.5 Sonnet flagged the ambiguity before generating tests in 95.0% of cases, preventing flawed assumptions from escaping sprint grooming.
-
Sub-1% Syntactic Hallucination: Gemini 1.5 Pro generated the highest error rate (4.4%), inventing non-existent payload keys (e.g.,
discount_override_auth) that were never mentioned in the Jira story. Claude maintained a 0.9% hallucination rate, strictly adhering to provided schema constraints. - 46% Faster Human QA Review Cycle: Because Claude's test matrices omit redundant duplicate cases and cleanly segregate boundary from functional planes, SDETs approved Claude test suites in an average of 4.2 minutes per ticket, compared to 7.8 minutes for GPT-4o and 9.5 minutes for Gemini.
Automating the Pipeline: Jira Webhooks to Claude API
Manual copy-pasting between Jira and a web browser chatbot is inherently unscalable. Modern engineering pipelines integrate Claude directly into Jira's ticket lifecycle using webhooks and workflow orchestrators like Atlassian Automation or self-hosted n8n:
-
1. Jira Status Transition Trigger
When a Jira ticket transitions from
In ProgresstoReady for QA, a webhook fires a JSON payload containing the summary, description, and custom acceptance criteria fields. -
2. Claude API Semantic Compilation
An automated service receives the webhook, injects the system prompt scaffolding, and queries Claude 3.5 Sonnet with
temperature: 0.1for deterministic, rigorous output. - 3. Automated Ticket Enrichment & Xray Sync Claude's response is parsed: the ambiguity audit is posted as a Jira comment tagging the author, while test cases are converted into linked Xray or Zephyr test entities for human QA review.
Where Claude Struggles: Critical Pitfalls to Avoid
While Claude excels at logical deduction, QA teams must remain vigilant against three persistent failure modes:
1. The "Blind Acceptance" Trap: If a product manager writes a flawed requirement in Jira, Claude will generate flawless test cases that diligently verify the flawed logic. Claude validates spec consistency, not whether the spec makes commercial or operational sense.
2. Undocumented Architectural State: Claude cannot anticipate unstated database constraints, microservice latency bottlenecks, or third-party payment gateway idiosyncrasies unless explicitly passed in the prompt context.
3. Flaky UI Selectors: If you ask Claude to write automated end-to-end Cypress or Playwright tests without providing the real DOM schema, it will hallucinate placeholder CSS selectors like button.checkout-btn-main that break on first run. As detailed in our review on How to Test AI-Generated Code Before It Reaches Your Live Website, automated pre-flight verification is indispensable.
Frequently Asked Questions
Key clarifications and practical answers addressed by The Indox editorial board.
Which Claude model is best for generating test cases from Jira?
Claude 3.5 Sonnet is currently the industry standard for test case compilation. It provides the optimal balance of deep logical reasoning, strict XML schema adherence, fast execution speed, and cost efficiency. For highly complex mathematical logic or multi-tiered regulatory workflows, Claude models with extended thinking allow the model to deliberate on combinatorial state permutations before outputting the test matrix.
Can Claude export test cases directly into Jira Xray or Zephyr?
Yes. By instructing Claude to format its final output as JSON adhering to the Xray REST API schema or Zephyr CSV import specifications, automated CI/CD jobs can directly post the generated test cases as sub-tasks or linked test entities associated with the originating Jira ticket.
Is it safe to send proprietary enterprise Jira requirements to Claude?
When utilizing Anthropic's commercial API or enterprise agreements (such as AWS Bedrock or Google Cloud Vertex AI), customer inputs and outputs are governed by strict Zero-Data-Retention (ZDR) contracts and are never used to train frontier models. However, teams should avoid pasting unredacted credentials, API keys, or personally identifiable customer data (PII) into browser consumer interfaces.
How does Claude compare to ChatGPT for QA test generation?
In The Indox AI's empirical benchmark of 40 enterprise Jira user stories, Claude 3.5 Sonnet significantly outperformed OpenAI's GPT-4o on boundary value capture rate (91.4% vs 73.1%) and specification ambiguity detection (95.0% vs 65.0%). While GPT-4o generates competent happy-path scenarios, it tends to make unstated assumptions and silently write tests around them. Claude acts as a strict requirements compiler, aggressively challenging missing parameters and delivering test suites that require 46% less human QA review time (4.2 minutes vs 7.8 minutes per ticket).
Final Takeaway: Claude as the Quality Multiplier
Can Claude generate test cases from Jira requirements? Absolutely. But the greatest value Claude brings is not merely saving twenty minutes of manual typing—it is forcing specification clarity earlier in the development lifecycle.
When Claude deconstructs a Jira ticket into equivalence classes and boundary limits, it instantly reveals the assumptions developers and product managers took for granted. By pairing automated Claude scaffolding with human QA intuition, software engineering organizations can shift quality verification left, catching defects before they ever escape the sprint backlog.
The 2026 AI Software Engineering Playbook →
Explore our master pillar guide on agentic coding, verification harnesses, and enterprise CI/CD integration models across the frontier software stack.