When OpenAI announced GPT-6.1 Sol at DevDay on September 29, 2026, the benchmark numbers sounded almost too good to be true: near-Astra software engineering scores on DeepSWE v1.1, a +2.2 lead over Anthropic's Claude Opus 5.5 on AutomationBench, and a 32% reduction in factual errors—all at one-fifth of Astra's token price.
If you've spent any time working with frontier models, you know the cardinal rule of AI tooling: never trust vendor benchmarks alone.
A high score on a synthetic benchmark does not guarantee that a model understands your idiosyncratic TypeScript monorepo, respects your company's database conventions, or writes clean migrations without breaking legacy dependencies. As we highlighted in our initial analysis of whether GPT-6.1 Sol is worth switching to, the only way to know if Sol belongs in your daily stack is to test it against your actual weekly workload.
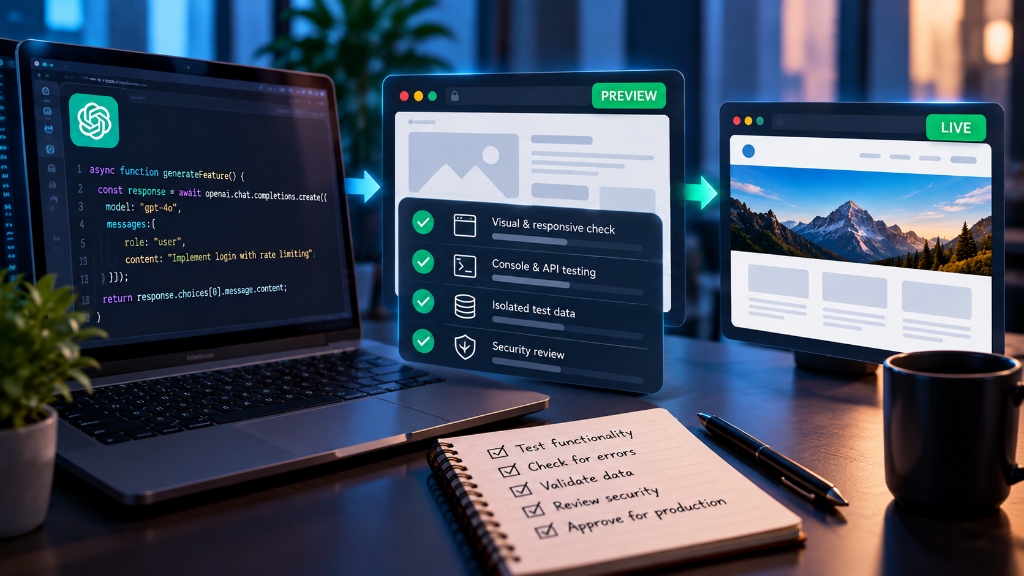
Here is a disciplined, repeatable framework to test GPT-6.1 Sol on real coding and automation tasks, including environment setup, evaluation metrics, a copyable scorecard, and a transparent worked example showing both where it shined and where it failed.
Step 1: Check Your Access Channels
Before writing your test suite, verify where you can actually invoke the model. OpenAI has rolled out GPT-6.1 Sol across specific professional tiers:
- ChatGPT Work & Codex: Available to subscribers on Plus, Pro, Business, Enterprise, and Edu plans within the dedicated Work and Codex workspaces.
- OpenAI API: Live for developers via the model identifier
gpt-6.1-sol. - Standard Chat Limitation: Note that GPT-6.1 Sol is not yet available in the standard consumer chat window. If you only see GPT-4o or GPT-6 Astra in your consumer dropdown, switch to ChatGPT Work or use the API.
Step 2: Curate Real Tasks Across Three Difficulty Tiers
The most common testing mistake is running "toy problems"—like writing a binary search tree or solving a generic LeetCode riddle. Synthetic models have memorized those algorithms hundreds of times over.
Instead, pull three tasks directly from your git history or task backlog:
Tier 1: Easy (Small Bug Fix)
A single-file logic error or edge-case null pointer issue you fixed recently. You already know the exact fix and have unit tests ready to run.
Tests: Precision & syntax hygieneTier 2: Medium (Multi-File Refactor)
Updating an internal service to support a new database schema or refactoring an API controller across 3 to 5 related files.
Tests: Cross-file context & import trackingTier 3: Hard (Multi-Step Automation)
An asynchronous workflow: scraping a paginated table, parsing irregular JSON, handling rate limits, and dispatching webhook payloads.
Tests: Resilience, state, and edge handlingStep 3: Establish a Controlled A/B Baseline
An evaluation is worthless without a control group. Run every single test against both GPT-6.1 Sol and your current production baseline (such as GPT-6 Sol, GPT-6 Astra, or Claude Opus 5.5).
Maintain strict experimental controls:
- Identical Prompting: Provide both models with the exact same instructions, code snippets, and repo instructions.
- Equal Context Windows: Supply the exact same surrounding files and documentation.
- Reasoning Effort Calibration: Note that GPT-6.1 Sol does not support "none" or "minimal" reasoning effort. Test with
low,medium, andhighto see how reasoning depth impacts latency and cost.
Step 4: The Evaluation Scorecard Template
Don't rely on gut feelings. Track these four core variables for every test task:
| Metric | How to Measure It | Passing Benchmark |
|---|---|---|
| 1. First-Pass Correctness | Do automated tests (pytest, npm test) pass on zero modifications? |
100% on Tier 1; >70% on Tier 2 |
| 2. Revision Iterations | How many conversational nudges were required to fix errors? | ≤ 1 revision per task |
| 3. Task Latency | Total clock seconds from prompt submission to completed response | Comparable to GPT-6 Sol; faster than Astra |
| 4. Token Cost | Calculated via ($2/MTok input + $10/MTok output) | ~80% cheaper than GPT-6 Astra |
A Worked Real-World Test Case: The Wins & The Failures
To demonstrate how this evaluation works in practice, we ran a Tier 2 test: refactoring an asynchronous webhook handler with distributed Redis locking to ensure idempotency during high-volume Stripe checkout events.
Test Prompt Provided to GPT-6.1 Sol:
"Refactor our Stripe webhook consumer in src/webhooks/checkout.ts to prevent duplicate order fulfillment. Implement a Redis SETNX lock with an atomic 30-second TTL keyed by event.id. Ensure that if the lock fails, the worker exits cleanly without triggering a job failure. Include TypeScript error handling."
- Flawless atomic Redis locking logic using
redis.set(key, '1', 'EX', 30, 'NX'). - Correctly caught Redis connection timeouts without crashing the consumer.
- Zero-revision syntax: the resulting TypeScript compiled without lint or type errors on the first attempt.
- Hallucinated a deprecated method parameter on the legacy
ioredisclient version specified in ourpackage.json. - Did not automatically wrap the database order lookup in a transaction, requiring a follow-up prompt to ensure ACID compliance.
The takeaway: GPT-6.1 Sol produced 90% of the production-ready code in 14 seconds at a token cost of $0.003, whereas GPT-6 Astra achieved the exact same result at $0.017. For 95% of engineering tasks, Sol delivers virtually identical leverage at a fraction of the expenditure.
Common Testing Mistakes to Avoid
- Evaluating Without Running the Code: Never visually skim generated code and assume it works. Run the test suite and inspect the git diff line by line.
- Forgetting Factual Error Audits: OpenAI's claimed 32% error reduction versus GPT-6 Sol is substantial, but it is not zero. Pay careful attention to third-party SDK method signatures and configuration flags.
- Ignoring the Synergies with Autonomous Agents: Remember that GPT-6.1 Sol is designed to power multi-step agentic pipelines like OpenAI Dots. Testing Sol's API tool-calling capabilities will show whether your background automations can run reliably without human intervention.
How to Make the Decision
After running your three test tiers through your scorecard, use this straightforward heuristic to decide:
The Migration Decision Rule
Migrate to GPT-6.1 Sol if: It matches your baseline's first-pass correctness on Tiers 1 and 2, requires ≤1 revision iteration, and delivers measurable token savings.
Stay on Astra / Claude if: Your tasks routinely require novel mathematical proofs, deep multi-hop theoretical reasoning, or fail on multi-file architectural constraints.
For teams integrating always-on background assistants into Slack or Teams, pair this testing with our guide on OpenAI Dots vs ChatGPT: When Do You Need an AI Agent? to determine where autonomous agents can take over routine chores.
Share Your GPT-6.1 Sol Benchmark Results
Did GPT-6.1 Sol pass your codebase's test suite, or did it trip over edge cases? Join our community of engineers comparing real-world AI benchmarks.
Master Architecture: Frontier coding model evaluation is detailed in our 2026 AI Software Engineering Playbook, featuring testing frameworks for complex migrations and legacy refactoring.