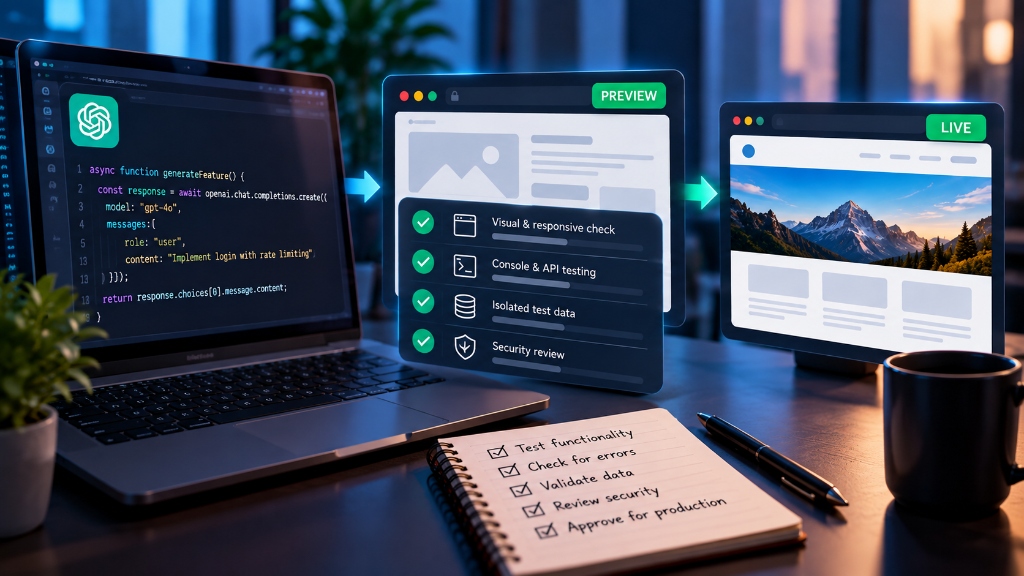
Every developer knows the subtle cognitive drag of waiting for an AI assistant to finish streaming code. You prompt your coding assistant to refactor an asynchronous pipeline, and for the next 12 to 20 seconds, you watch tokens crawl onto the screen. In that brief window, your focus fractures: you check Slack, peek at an open browser tab, or lose your train of thought.
When OpenAI unveiled its Ultrafast tier alongside GPT-6.1 Sol on September 29, 2026, the headline promise sounded like an engineer's dream: up to 8x faster token generation in Codex and 6x in the API.
The natural assumption is that 8x faster token generation must translate directly into dramatically faster software delivery. But does it?
The short answer: Sometimes, but speed alone will not shorten your overall software development lifecycle.
While sub-second token generation eliminates the psychological friction of interactive coding, software engineering is governed by bottlenecks that no language model can outrun. Here is an honest, architectural look at where faster AI inference genuinely accelerates development, where it fails to make a dent, and why paying a 6x premium requires careful economic calculation.
What Is OpenAI Ultrafast, and What Does It Cost?
First, it is essential to understand what Ultrafast is—and what it isn't. Ultrafast is not a new model architecture. It is a premium infrastructure and serving tier that allocates dedicated, highly optimized compute clusters to stream tokens at extreme speeds.
- GPT-6 Astra: Live today in Codex, ChatGPT Work, and standard API endpoints.
- GPT-6.1 Sol: Announced for Ultrafast rollout in "the coming days"; early API integration notes confirm it is still rolling out progressively.
- Interface Access: Available exclusively on the new Pro 500 plan (25x the rate limits of Plus) or custom Enterprise contracts.
- Token Premium: Ultrafast token generation costs roughly 6x more than standard tier pricing.
- Base Model Advantage: GPT-6.1 Sol is priced at ~one-fifth the cost of Astra, partially offsetting the tier multiplier.
- Context Caching: Cached inputs remain highly affordable at $0.10 per million tokens (95% discount), crucial for persistent coding contexts.
By decoupling speed from base intelligence, OpenAI is establishing latency as a distinct commercial dimension alongside reasoning depth and context window size.
Where Faster AI Responses Genuinely Accelerate Work
Speed is not useless; for specific developer workflows, low-latency generation creates a qualitative leap in developer satisfaction and immediate productivity.
1. Preserving "Developer Flow State"
Cognitive science consistently shows that when a system responds in under 500 milliseconds, users perceive the interaction as instantaneous. Between 1 and 2 seconds, developers maintain their train of thought. Once waiting time stretches past 10 seconds, attention wanders.
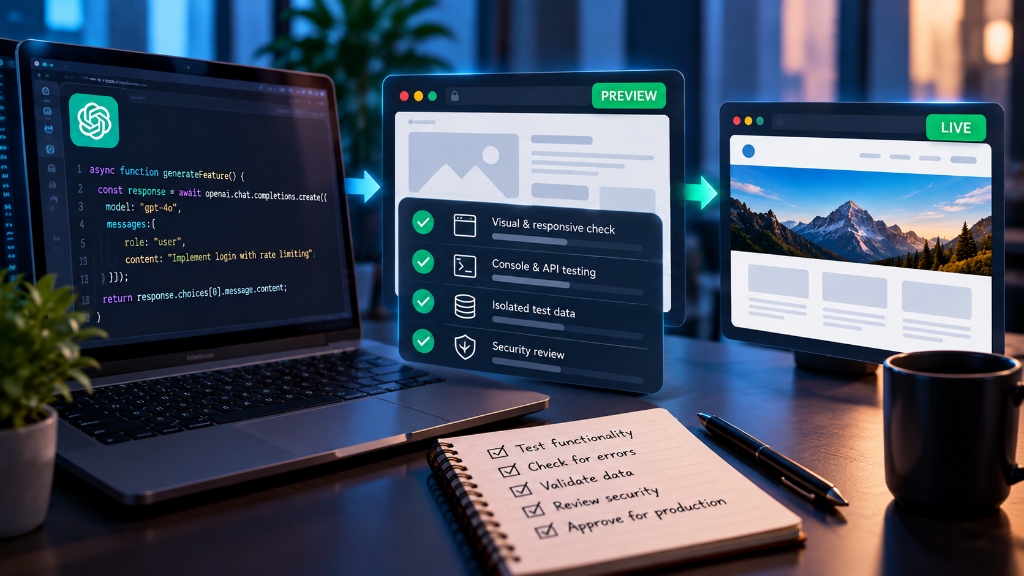
When you are iterating inside an IDE—asking Codex to rewrite a regex, scaffold a mock database fixture, or debug a cryptic TypeScript compiler error—receiving the complete diff in 1.5 seconds instead of 12 seconds keeps your brain locked into the problem. You remain in active problem-solving mode rather than reactive waiting mode.
2. Rapid-Fire REPL and Debugging Loops
During active debugging, developers often execute tight conversational feedback loops:
- "The test failed with a NullReferenceException on line 42—inspect the caller."
- "Add guard clauses for empty arrays."
- "Show the updated mock payload."
When each conversational turn takes 15 seconds, a 4-turn troubleshooting sequence burns a full minute of pure idle time. At Ultrafast speeds, those four turns execute in under 10 seconds total, making the assistant feel like an extension of local compiler tooling.
Why Speed Fails to Shorten the Entire Development Cycle
To understand why an 8x generation speedup does not produce an 8x faster feature release, we must look at where software engineering time is actually spent.
📐 Amdahl's Law of Developer Productivity
In computer science, Amdahl's Law dictates that the overall performance improvement gained by optimizing a single component of a system is strictly limited by the fraction of time that component is utilized. If writing raw code represents only 15% of your total development cycle, speeding up code generation by 8x only improves overall delivery speed by approximately 13%.
Consider the full journey of a software pull request from inception to production deployment:
| SDLC Stage | Typical Time Investment | Impact of 8x AI Generation Speed |
|---|---|---|
| 1. Requirements & System Design | 20% - 30% of total effort | Zero impact (Requires human stakeholder alignment) |
| 2. Active Code Generation & Prompting | 10% - 15% of total effort | Massive speedup (Reduced from minutes to seconds) |
| 3. Code Comprehension & Verification | 25% - 35% of total effort | Potential slowdown (More generated code to read and audit) |
| 4. Automated Testing & Local Verification | 15% - 20% of total effort | Zero impact (Bound by test suites and runtime execution) |
| 5. Peer Code Review & CI/CD Pipelines | 15% - 25% of total effort | Zero impact (Bound by human availability and build queues) |
Generating 300 lines of robust Go or Rust code in 2 seconds is an impressive engineering feat. But that code must still be understood by the developer submitting it, pass integration tests, survive security linting, be reviewed by a tech lead, and progress through staged staging environments.
Inference latency was never the primary bottleneck in the software lifecycle.
The Quality Paradox: Hallucinating at Record Velocity
There is another, more dangerous risk to optimizing solely for generation speed: speed magnifies flaws.
OpenAI noted that GPT-6.1 Sol lowered its factual error rate on deliberately difficult prompts from 11.4% down to 7.7% at low reasoning effort. While that is a commendable 32% reduction in hallucinations, a 7.7% error rate still means that roughly 1 in every 13 complex assertions or code structures contains an inaccuracy.
⚠️ The Velocity Trap
If an AI model generates flawed code 8x faster, an undisciplined developer will accept flawed code 8x faster. Spending 30 seconds waiting for thoughtful code generation is vastly superior to spending 45 minutes debugging an obscure concurrency bug introduced by a split-second hallucination.
On benchmarks like DeepSWE v1.1, GPT-6.1 Sol achieves approximately 75%, slightly edging out Claude Sonnet's 71% and competing with Claude Opus 5.5. However, benchmarks represent synthetic environments. In enterprise codebases with legacy dependencies, custom internal frameworks, and sparse documentation, model reasoning depth matters far more than token velocity.
Interactive Coding vs. Autonomous Agents: When Speed Actually Matters
Whether OpenAI's Ultrafast tier justifies its 6x price tag depends entirely on your execution mode:
🟢 Interactive "In-the-Loop" Coding
Context: Developer is seated in the IDE, waiting for every token to land.
Speed Sensitivity: Extremely High.
Verdict: High ROI. Paying extra to preserve developer focus, avoid context switching, and accelerate short debugging loops is well worth the token cost.
⚪ Autonomous "Out-of-the-Loop" Agents
Context: Background agents like OpenAI Dots or overnight test generators running unattended.
Speed Sensitivity: Low to Moderate.
Verdict: Low ROI. If an agent runs while you sleep, paying a 6x premium for the job to finish at 2:05 AM instead of 2:30 AM is a financial waste.
How Engineering Teams Should Test It: An Empirical Framework
Because independent real-world productivity benchmarks for DevDay's releases do not yet exist, teams should conduct their own timing and cost-benefit experiments before upgrading entire developer organizations to Pro 500 or Ultrafast API keys.
Here is a standardized 5-step testing framework your team can run this week:
Select 3 Standardized Workloads
Choose three concrete tasks from recent sprints: a targeted bug fix (isolated scope), a multi-file refactor (dependency changes), and a brand-new feature endpoint with database migrations.
Run Side-by-Side Trials with Identical Prompts
Have two developers (or one developer across consecutive days) execute the tasks using identical models (e.g., GPT-6 Astra) on Standard speed versus Ultrafast.
Measure Total Wall-Clock Time to PR Approval
Do not measure token streaming duration in isolation. Measure wall-clock time from the initial prompt until the code is reviewed, tested, and passing all CI checks.
Track Revision Cycles & Defect Rates
Count how many times the developer had to re-prompt or manually patch the generated code. Did speed encourage careless prompt thrashing?
Calculate the True ROI
Compare the dollar cost of developer time saved (e.g., $100/hr) against the 6x token cost multiplier. If a developer saves 5 minutes on a task but burns $12 in extra API tokens, the unit economics are negative.
The Verdict: A Quality-of-Life Win, Not a Lifecycle Revolution
OpenAI's Ultrafast tier and GPT-6.1 Sol represent an undeniable triumph of infrastructure engineering. Eliminating latency in developer tools is a profound quality-of-life improvement that reduces cognitive fatigue and keeps engineers immersed in their code.
However, engineering leadership must not confuse token generation velocity with software delivery velocity.
The true constraints of software development remain human and structural: architecture definition, system integration, edge-case testing, and peer review. Faster AI responses help you eliminate the waiting room—but you still have to drive the car.
Empower Your Engineering Team with Pragmatic AI Insights
Stay ahead of real-world benchmarks, token economics, and hands-on developer tooling comparisons across OpenAI, Anthropic, and open-source models.
Master Architecture: Latency ergonomics and developer flow states are featured in Track 1 of our 2026 AI Software Engineering Playbook, examining prompt caching economics and async agent delegation.